 Philip Mou
I built AI Portfolio Analytics because I wanted one place to compare a portfolio, look at its risks, and ask questions about the results. The project started in November 2024 and has grown into a full-stack web application.
- My role
- Personal full-stack project
- Frontend
- React, Material UI, Chart.js, Recharts
- Backend
- Python, Flask, Pandas, NumPy
- Data & hosting
- PostgreSQL, SQLAlchemy, nginx
What it does
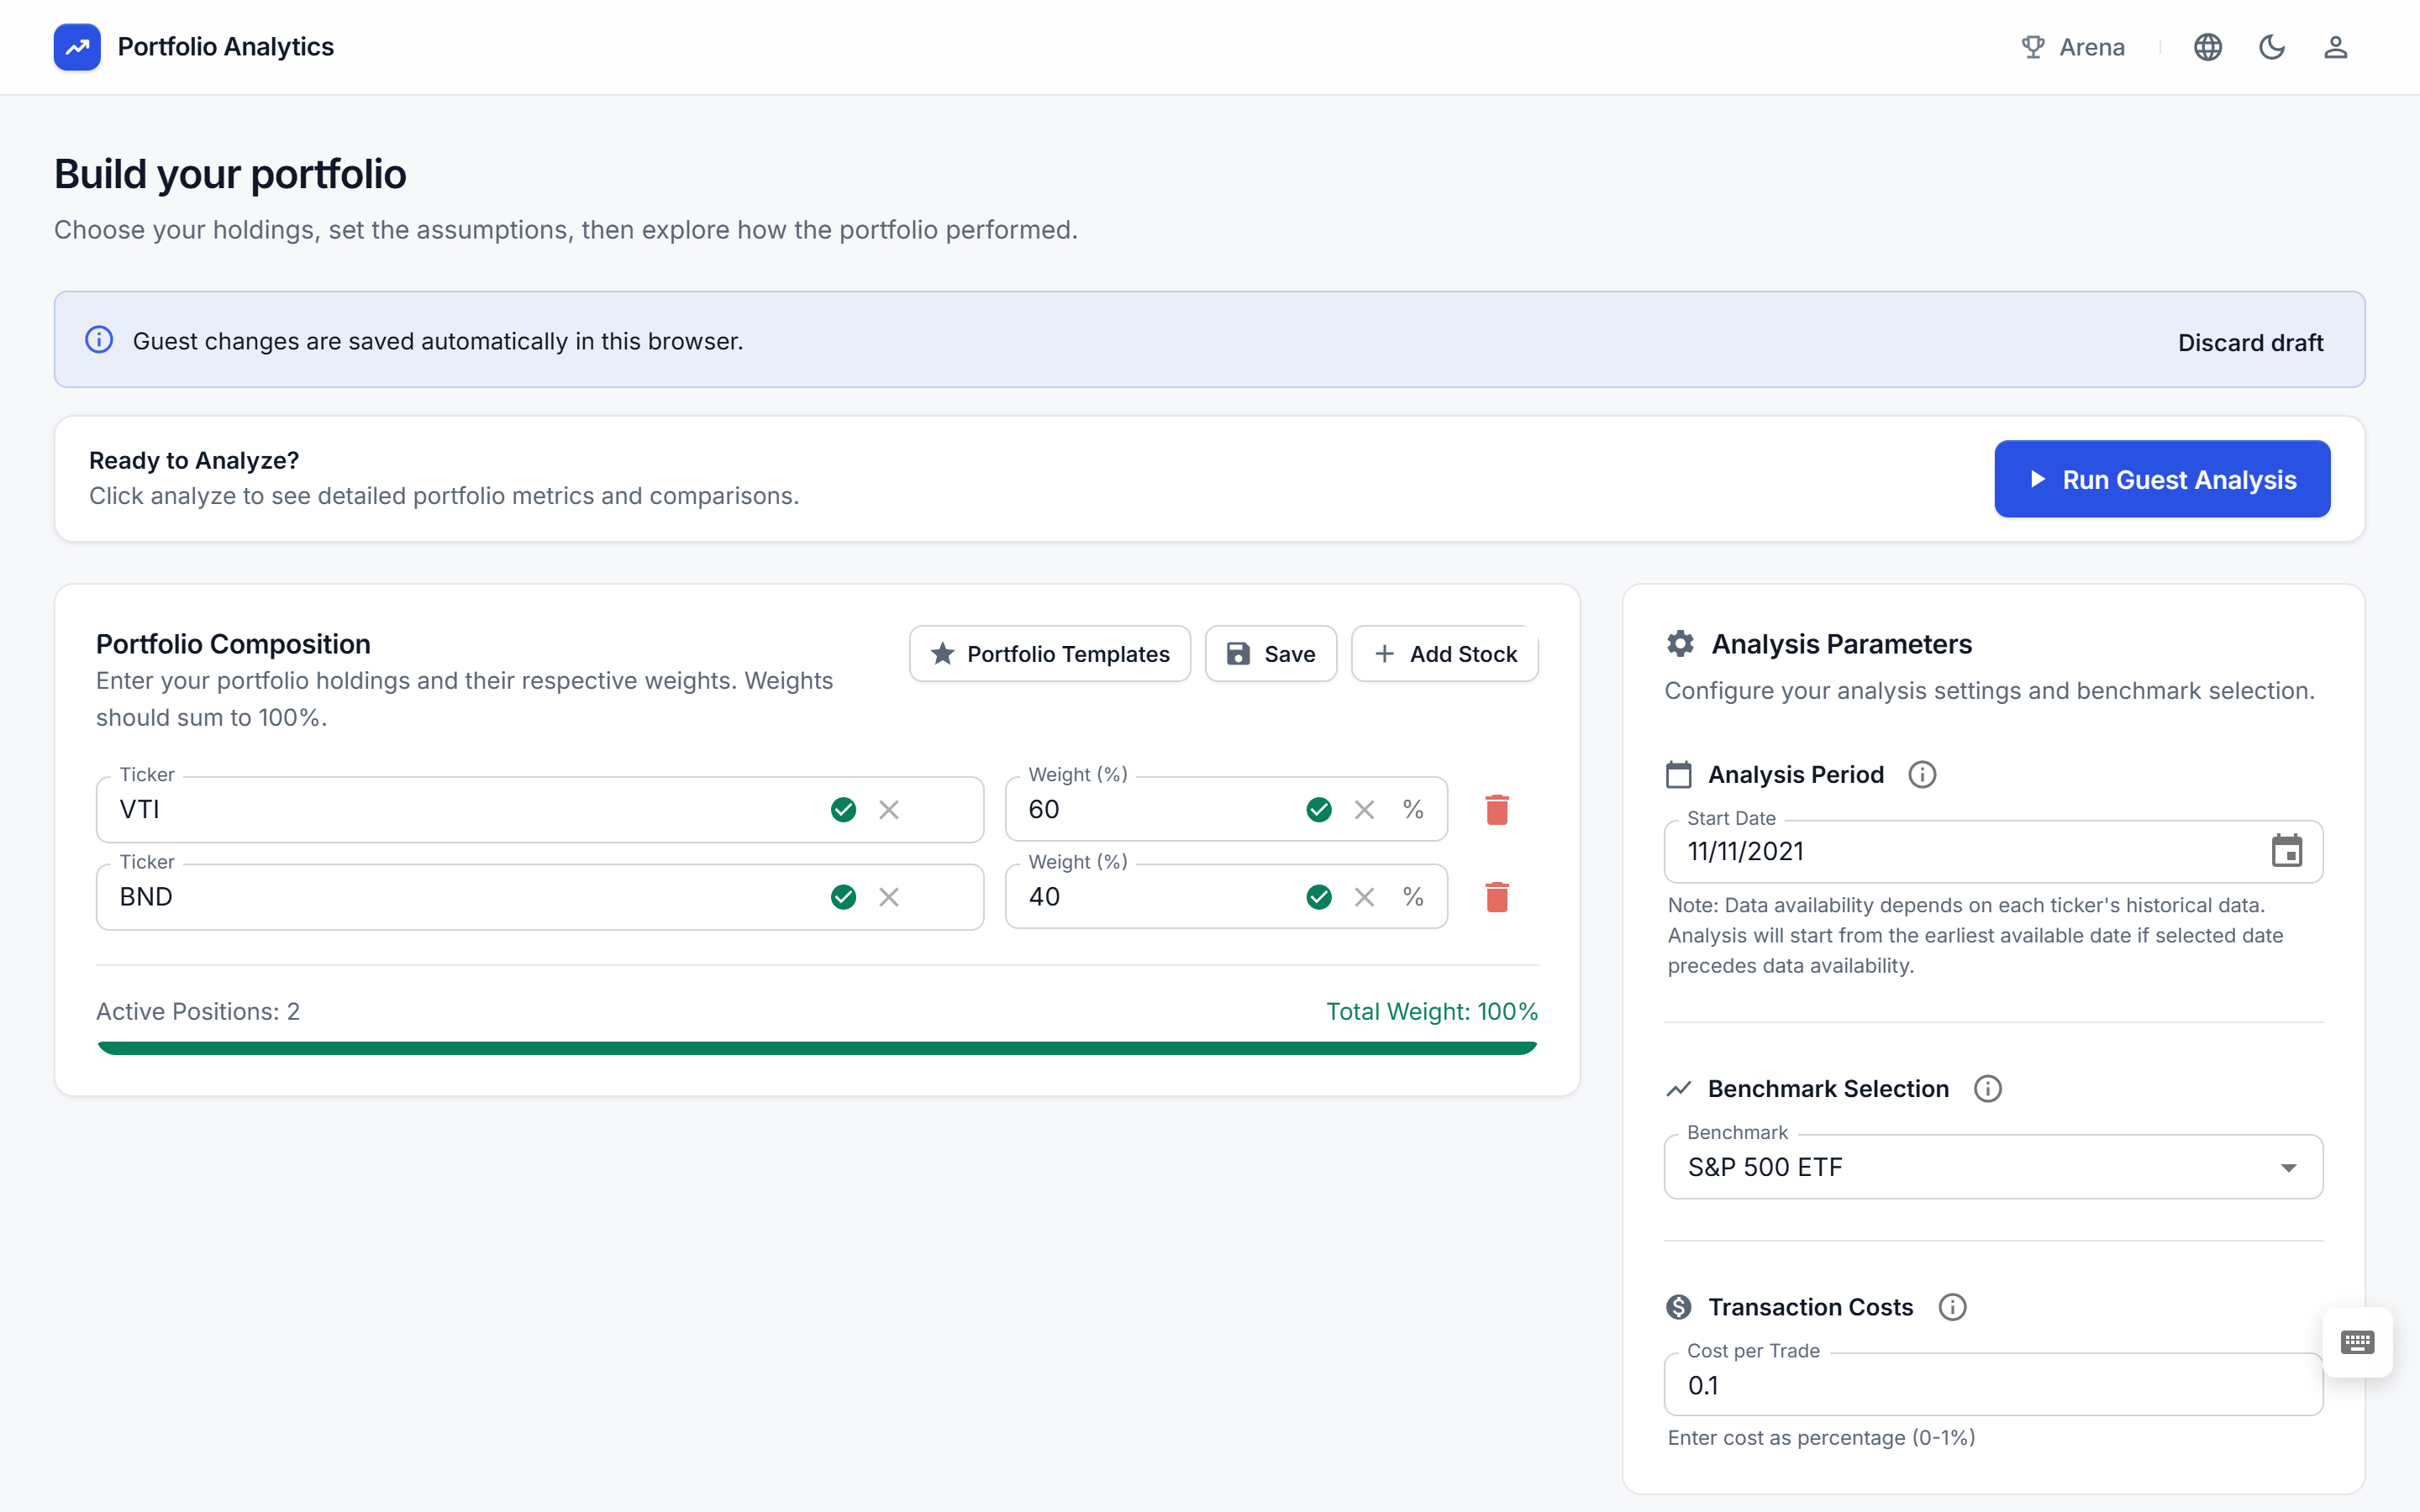
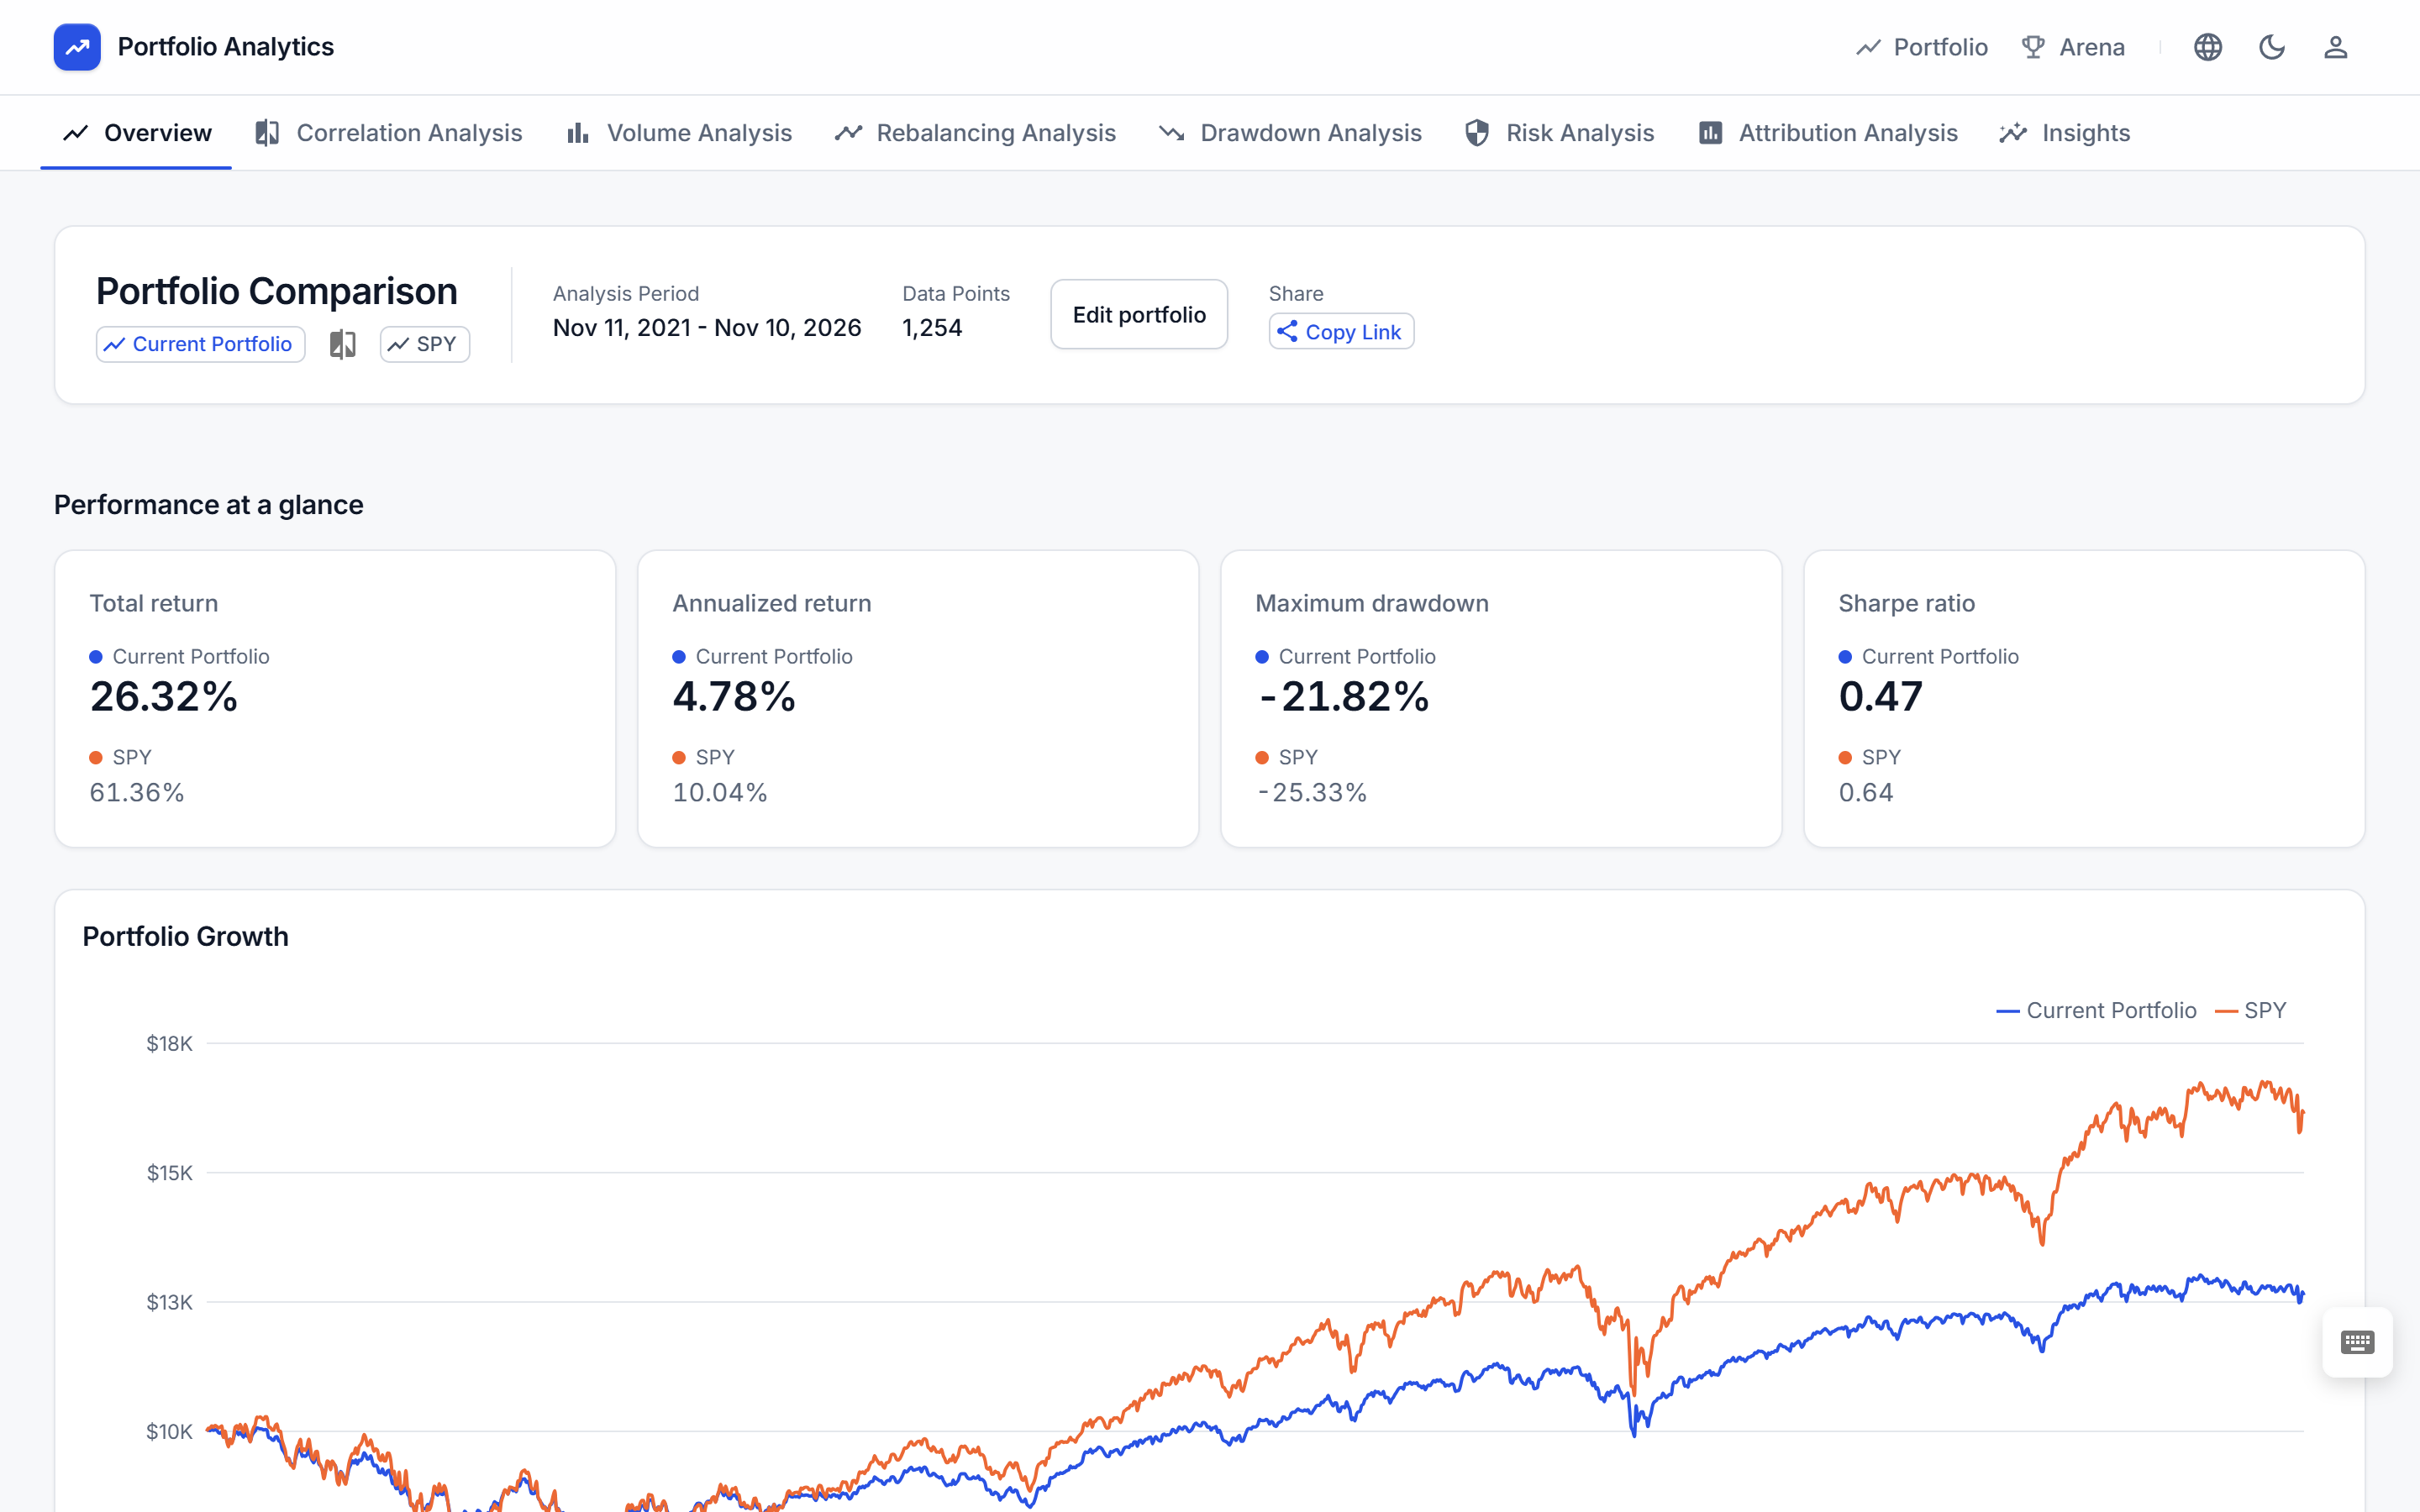
You enter a set of stocks or ETFs, assign weights, and choose a comparison period and benchmark. The application then brings together portfolio performance, drawdowns, correlations, and other risk measures. AI-generated explanations sit alongside those results.
There are templates for getting started and manual controls for people who already have an allocation in mind. The interface also exposes separate historical simulation and paper-trading tools; those require sign-in.
How the pieces fit together
- React handles the input and results. Portfolio holdings, weights, date ranges, and benchmark choices are sent to the Flask API. Charts and tables give the calculations a usable interface.
- The backend prepares the data. It collects the unique tickers, fetches price history, and checks the available dates and data before processing the portfolios.
- Python calculates the metrics. Pandas and NumPy support the analysis, including returns, volatility, historical drawdowns, and correlations.
- The AI layer explains the results. Analysis services generate commentary for the different result sections. Streaming endpoints and progress updates help the interface handle longer requests.
- Results can be reused. The backend hashes the analysis parameters and looks for a matching cached result before repeating the calculation.
The boundary between calculations and AI
The numerical analysis and the generated explanation are separate parts of the application. Portfolio metrics are calculated in Python. The language model adds commentary and helps users ask questions about the results.
For generated portfolio allocations, the backend checks the response structure and required fields, validates holdings and weights, and normalizes the allocation. A model response still has to fit the application’s expected data format.
That boundary matters. An explanation can sound convincing without being reliable, and historical results do not establish what a portfolio will do next. The AI output needs to be read alongside the underlying data and assumptions.
Details that matter once it runs
Simulation costs: orders need room for fees and slippage. Allocating every last dollar can cause an otherwise valid purchase to be rejected. I check single-asset and mixed portfolios against small, repeatable price series so that order execution and reported returns agree.
Data availability: different tickers have different histories. The request flow needs to account for missing data and the usable analysis period, rather than quietly treating every series as complete.
Repeated requests: caching by analysis parameters lets the backend return a saved result when the same inputs are used again. The response identifies when it has come from the cache.
Longer analysis: calculation and AI generation do not always finish at the same time. Progress tracking and streaming provide feedback while the work is still running. The nginx configuration also has to support that streaming response.
Keeping AI usage bounded: numerical comparisons are available as a guest. AI requests require a verified account and spend credits, with a small signup allowance and daily check-in reward. The API reserves credits before a request, prevents duplicate charges, and refunds failed calls. Usage and concurrency limits still apply when someone calls the API directly.
What I’d improve next
I’d put more work into making the evidence behind an AI explanation easier to inspect: the input data, the relevant metric, and the assumptions used. I’d also expand the evaluation around incomplete price histories and generated explanations, so changes can be checked against repeatable examples.
This is a personal software project, not a claim of investment performance. The part I want to show here is how the interface, data processing, numerical analysis, and AI services fit together.